RAG in Three Steps: How Retrieval Works, Where It Breaks, and What Comes Next
Abstract
Retrieval-augmented generation, RAG for short, hands a language model the texts it never saw in training, found through numerical similarity. We work through how that similarity is computed, why it so often returns the wrong passage, and which three routes lead out of the problem. The failures come from semantic nearness that is not relevance, texts of very different length, and the bias-variance trade-off in embeddings with more than a thousand dimensions. Of the three routes we consider the last one, a knowledge graph with logical relations, the most promising.
A language model knows what was in its training data and nothing else. That is a fine arrangement until you want an answer about last week, or about the contracts in your own archive. The usual remedy is to find the relevant text first and hand it over together with the question.
Similar means close
A separate model turns a text into a list of numbers, an embedding or vector. The list is long: a standard embedding gives every text 1,536 numbers. On its own that does not help much. It starts to help once you read the list as a position. With two numbers you can mark a point in an ordinary coordinate system and draw an arrow from the origin to it; with 1,536 numbers the coordinate system is one we cannot picture, but the principle stays the same. For any two points you can calculate the distance. The closer they are, the more similar the two texts are supposed to be.
Where do the numbers come from? Heavily simplified, from watching which words turn up together. Take "The cat sits under the table" and a context window of one word on either side. Cat and the occur in the same context, cat and sits do too, cat and table do not. A neural network is trained on huge numbers of such pairs until its internal weights settle into a stable vector for each word and passage.
In a running system, the user's question is converted the same way, the nearest stored texts are looked up, and they are added to the model's input. That is the whole mechanism. The model learns nothing after training; RAG works around this by trying to make sure the right pages are lying on its desk before it speaks.
Close is not relevant
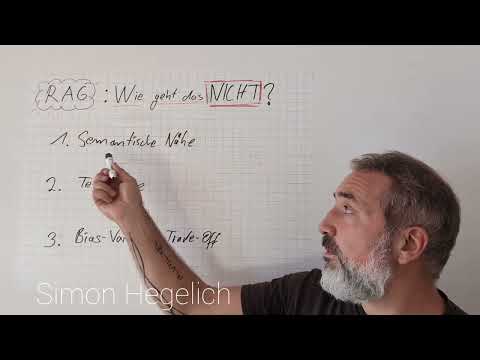
RAG is a statistical shortcut, and three structural problems explain why it so often breaks down.
Semantic nearness. The similarity is computed from shared context, and shared context is cheap. Ask which diet an overweight cat should be on, and a text about dog diets sits right next to it in vector space: both are pets, both come with nutritional advice, both turn up in the same kind of sentence. The geometric nearness is real, and the help is none. In the worst case the model answers with advice that works for dogs and harms cats.
Text length. An embedding is computed from all the words in a passage, so a long text ends up with a more balanced, more average position in the vector space than a short query. It gets worse when you compare short texts with long ones because of Zipf's law: a few words (and, the, of) are extremely frequent and carry no topical weight, while domain-specific words are rare and have poorly learned representations. Long passages get pulled toward a bland middle.
Bias and variance. With 1,536 dimensions, the representation has very low bias — the space is rich enough to express subtle differences — but very high variance, since every one of those 1,536 coordinates fluctuates. Then standard retrieval compresses that entire 1,536-dimensional space into a single number: the scalar distance between two vectors. All the directional richness spent on building the embedding is collapsed into one average distance, and with it goes the exact distinction you were looking for.
That is why so many teams report poor experiences with flat RAG in production. What comes back is superficially similar at best and, at worst, drawn from a context whose underlying assumptions no longer hold.
Three ways out
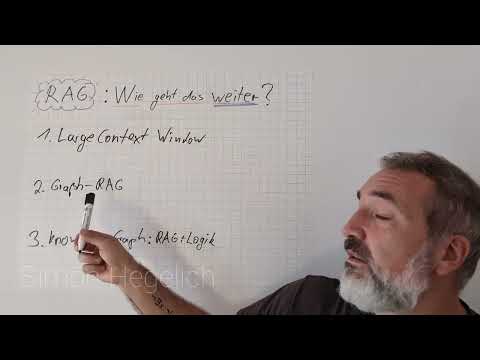
There are three routes out of this bottleneck, and no secret about which one we build toward.
Large context windows. Stop retrieving: if the model can read a million tokens at once, hand it the whole collection every time. Training and inference become far more expensive, and a deeper issue appears that we call attention collapse. Because attention works on statistical correlations learned mostly from short texts, a model struggles to weigh what matters far back in a massive prompt. Early tokens dominate, middle passages fade, and the whole calculation stays locked inside an un-auditable black box.
Graph-RAG. If long texts distort embeddings, cut them into smaller sections, embed each section, and link adjacent sections in a graph. When retrieval lands on a passage that is close in meaning but incomplete, the graph lets you pull in the section before and the section after. That helps with length, but notice how thin the relation is: saying that section B follows section A is something an ordinary database table already knows. The logical density is still near zero.
A knowledge graph with logic and coordinates. The third route connects retrieval with an explicit logical structure. A statement written by a user or derived by an agent does not just sit at a point in vector space; it stands in a determinate logical relation to other statements — identity, refinement, or contradiction. And it carries its provenance: who produced it, under which objective, and from which line of reasoning. When a system queries memory, it no longer asks only what sounds similar? It can ask: which verified statements share this context, and which recorded insights directly contradict this assumption?
Where this leads in our work
The distinction at the heart of this note — that similarity is not relevance, and that a memory worth keeping must preserve the logical context in which an insight was formed — became the sixth law of our mathematical theory of open-ended intelligence (Note #06). In our recent retrieval sweeps across more than three thousand multi-turn reasoning steps, we saw the failure mode of flat retrieval firsthand: pulling in early answers by raw similarity repeated initial mistakes and dragged accuracy down, whereas separating structural reach from how a memory is read kept the reasoning clean.